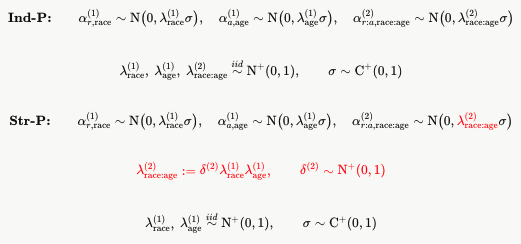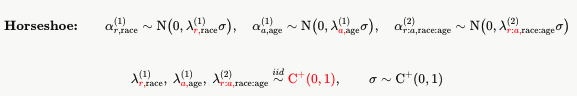Last week we talked about The Big Changes Coming to the Times/Siena Poll:
- New weighting variable: support score = E(2024 vote | other X variables).
- New weighting method: energy balancing (Huling & Mak, 2024)
Ben Schneider helpfully blogged about energy balancing as well:
Raking and similar calibration methods are based on balancing means or totals for specific variables…The energy balancing method does something different: it calibrates based on an entire multivariate distribution, as measured by an empirical cumulative distribution function (ECDF).

Jared Huling (of Huling & Mak, 2024) helpfully answered questions in the comments. I’m still puzzling over how energy balancing handles empty cells (unsampled regions of the joint covariate space). I need a toy example.
Consider 2 binary variables, so 4 population cells, with known population shares:
       k=0    k=1    total
j=0    .4     .2     .6
j=1    .2     .2     .4
total  .6     .4
Say the sample is missing folks in cell 11:
       k=0    k=1    total
j=0    .5     .3     .8
j=1    .2     0      .2
total  .7     .3
Consider 4 methods:
1. Classical Poststratification: not defined because of division by 0.
2. Raking: match only the margins. Correct when Y | X1, X2 is additive.
       k=0    k=1    total
j=0    .2     .4     .6
j=1    .4     0      .4
total  .6     .4
3. Energy balancing: minimize the Energy-Distance(F_w, F_pop) between the weighted sample distribution of X1, X2 and the population distribution. Correct when Y | X1, X2 is such that nearby cells have similar means.
Say X1 = young/old, X2 = man/woman, Y = percent Democrats, and no old women are sampled.
Raking is correct when additivity holds: old women = young women + (old men − young men)
Energy balancing is correct approximately when: old women = (old men + young women)/2 ?
library(WeightIt)

pop  <- data.frame(X1 = rep(c(0, 0, 1, 1), c(40, 20, 20, 20)),
                   X2 = rep(c(0, 1, 0, 1), c(40, 20, 20, 20)))

samp <- data.frame(X1 = rep(c(0, 0, 1), c(50, 30, 20)),
                   X2 = rep(c(0, 1, 0), c(50, 30, 20)))

dat <- rbind(cbind(pop,  A = 1),
             cbind(samp, A = 0))

W <- weightit(A ~ X1 + X2, data = dat, method = "energy",
              estimand = "ATT", focal = "1",
              dist.mat = as.matrix(dist(dat[, c("X1", "X2")])))

w <- W$weights[dat$A == 0]
tapply(w, interaction(samp$X1, samp$X2), sum) / sum(w)
       k=0    k=1    total
j=0    .381   .309   .69
j=1    .309   0      .309
total  .69    .309
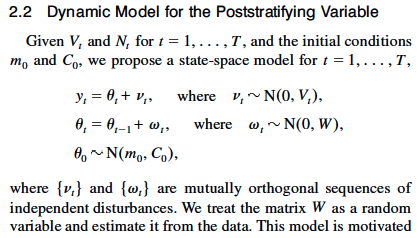
4. MRP: fit a model for Y | X1, X2. The interaction term’s posterior equals its prior, propagating uncertainty around additivity.
Am I understanding this correctly ?