Poststratification uses population data on X to estimate E(Y) via E(E(Y | X, R = 1)), where R = 1 are survey respondents who provide Y and X. When the inner expectation “E” is estimated via Multilevel Regression, this is called MRP. The outer “E” needs p(X), population data on X.
Sometimes we have to estimate the population distributions. We’ve seen a few examples:
- “2 flavors of calibration”: Say we have p(X), but we also need p(Z | X), the population distribution of another variable Z. We can estimate p(Z | X, R = 1) using survey data, but nonresponse could make this unreliable. Say we have population data on aggregates p(Z) (e.g. from census tables), then we can logit-shift to anchor to the population aggregate. See Kuriwaki et al. 2024.
- “MRPW”: Say we have p(X), but we also need p(W | X), the population distribution of the survey weights W. We can estimate p(W | X, R = 1) using survey data. Then because we assume survey weights are proportional to inverse probability of response 1/p(R = 1 | W, X), we can get what we need by Bayes Rule.
- “weights and MRP for voters”: Say we have p(X), but here we need p(X | V = 1), the distribution of X among the population of voters. By Bayes Rule we can get this via p(X) and p(V = 1 | X). The latter can be estimated from population turnout history and vote intent among survey takers.
In all cases, we have some anchor to the population, e.g. via aggregate totals, survey weights, or turnout history. This brings me to Andrew’s post asking 2016 pollsters to poststratify on party ID. We don’t have population aggregates to logit-shift to. But Andrew comments:
party ID is changing much more slowly than the distribution of vote preference, which itself is changing much more slowly than differential nonresponse.
So in our sample party ID (Z) is changing over time quickly, but mostly due to differential nonresponse:
p(Z | t, R = 1) = p(R = 1| Z, t)/p(R =1 | t) * p(Z | t) = differential nonresponse at t * party ID at t
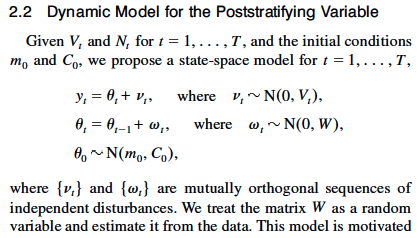
Andrew cites his coauthored paper Reilly et al. 2001, which fits a model to smooth the poststratifying variable Z over time. This won’t help with the component of differential nonresponse that is constant or slowly changing over time, but it prevents the polls from jumping around with every swing in differential nonresponse.
Andrew also cites his coauthored paper The Mythical Swing Voter, which uses 2008 exit poll data on Z to adjust polls from 2012. This also relies on the assumption that Z changes slowly over time, our anchor in the absence of population data.
We’ve been talking about adjusting for party ID. Another variable we might want to adjust for is interest in politics. In “adjusting for interest in politics” we cite Andrew and Gustavo‘s Challenges in Adjusting a Survey That Overrepresents People Interested in Politics. They see an increase over time in interest in politics, which they say could be nonresponse bias (people more interested in politics taking surveys) and/or a change in the population due to increased political polarization.
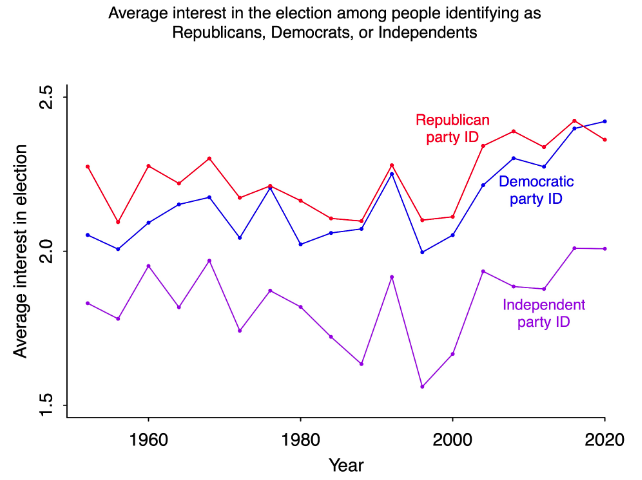
I’ve been scratching my head over this for two days now: How do you adjust (I’m assuming online polling) for the fact that people with no interest in elections might be less likely to respond in the first place?
Olaf:
There are different ways to do this adjustment. One approach is to poststratify on variables associated with interest in politics, such as voting history (whether respondents voted in previous primary and general elections).
What I’ve always somewhat thought is missed with post stratification which is often difficult to fully adjust for is that all your many variables are somewhat just proxies. For example if likelihood of response is caused by being liberal and you post stratify largely by party you’ve still likely got too many liberal republicans and too few conservative democrats. To my non practitioner eyes it feels bound to always under adjust.
Great point, Vicente ! I think this is empirically supported e.g. by results from “Disentangling Bias and Variance in Election Polls” by Shirani-Mehr, Rothschild, Goel, and Gelman. In election polls from 1998 to 2014, they found “substantial average election-level absolute bias, approximately 2 percentage points for senatorial and gubernatorial elections and 1 percentage point for presidential elections.” That is, whatever adjustment folks are doing is insufficient.
Great question, Olaf ! Andrew is right, turnout history is available through voterfiles and we used this as a proxy for political engagement in this post: https://statmodeling.stat.columbia.edu/2025/05/16/struggles-with-surveying-nonvoters-and-young-voters/